Partnerships7 min read
Thrifty Studios × ElevenLabs Eleven v4: giving the most expressive voice a face
 Thrifty AI Engineering
A voice can carry most of the emotion in a conversation. A face tells you whether to believe it. When ElevenLabs released Eleven v4 at the end of September, we spent a week pairing it with our Maya face models in Thrifty Studios. This post is what we learned: what is new in v4, how the pieces fit together, and the practical patterns we now recommend to customers.
What is Eleven v4?
Eleven v4 is ElevenLabs' newest text-to-speech generation, released in two flavours. Eleven v4 is tuned for produced content where quality matters most. Eleven v4 Turbo is tuned for real-time use and voice agents. According to ElevenLabs, v4 follows natural-language direction and inline audio tags more reliably than v3, holds a voice's identity across 90+ languages, and brings back Professional Voice Clones.
| Eleven v4 | Eleven v4 Turbo | |
|---|---|---|
| Built for | Produced content: courses, explainers, presenter intros | Live conversation and voice agents |
| Latency (per ElevenLabs) | Not optimised for live turn-taking | About 150 ms median time to first speech |
| Streaming | Streaming and non-streaming endpoints | Bidirectional streaming: send text as the LLM writes it |
| Audio tags | Yes, e.g. [whispers], [laughs], [pause] | Yes |
| Use in Thrifty | Async videos and course lessons in Studio | Real-time AI humans on web, Meet, kiosks |
Why does an expressive voice need a face?
Take the line "I thought you'd come back." Said softly, it is relief. Said clipped, it is an accusation. A voice-only agent can carry that difference, but the listener has to work to read it. Add a face whose mouth, cheeks and eyes move with the delivery, and the meaning lands instantly.
That is the job Maya does. Our face models are driven directly by the audio the user hears, frame by frame. When v4 slows down, breathes or laughs, the face moves with it. You don't have to choreograph gestures; you direct the voice and the face follows.
How does Eleven v4 work inside Thrifty Studios?
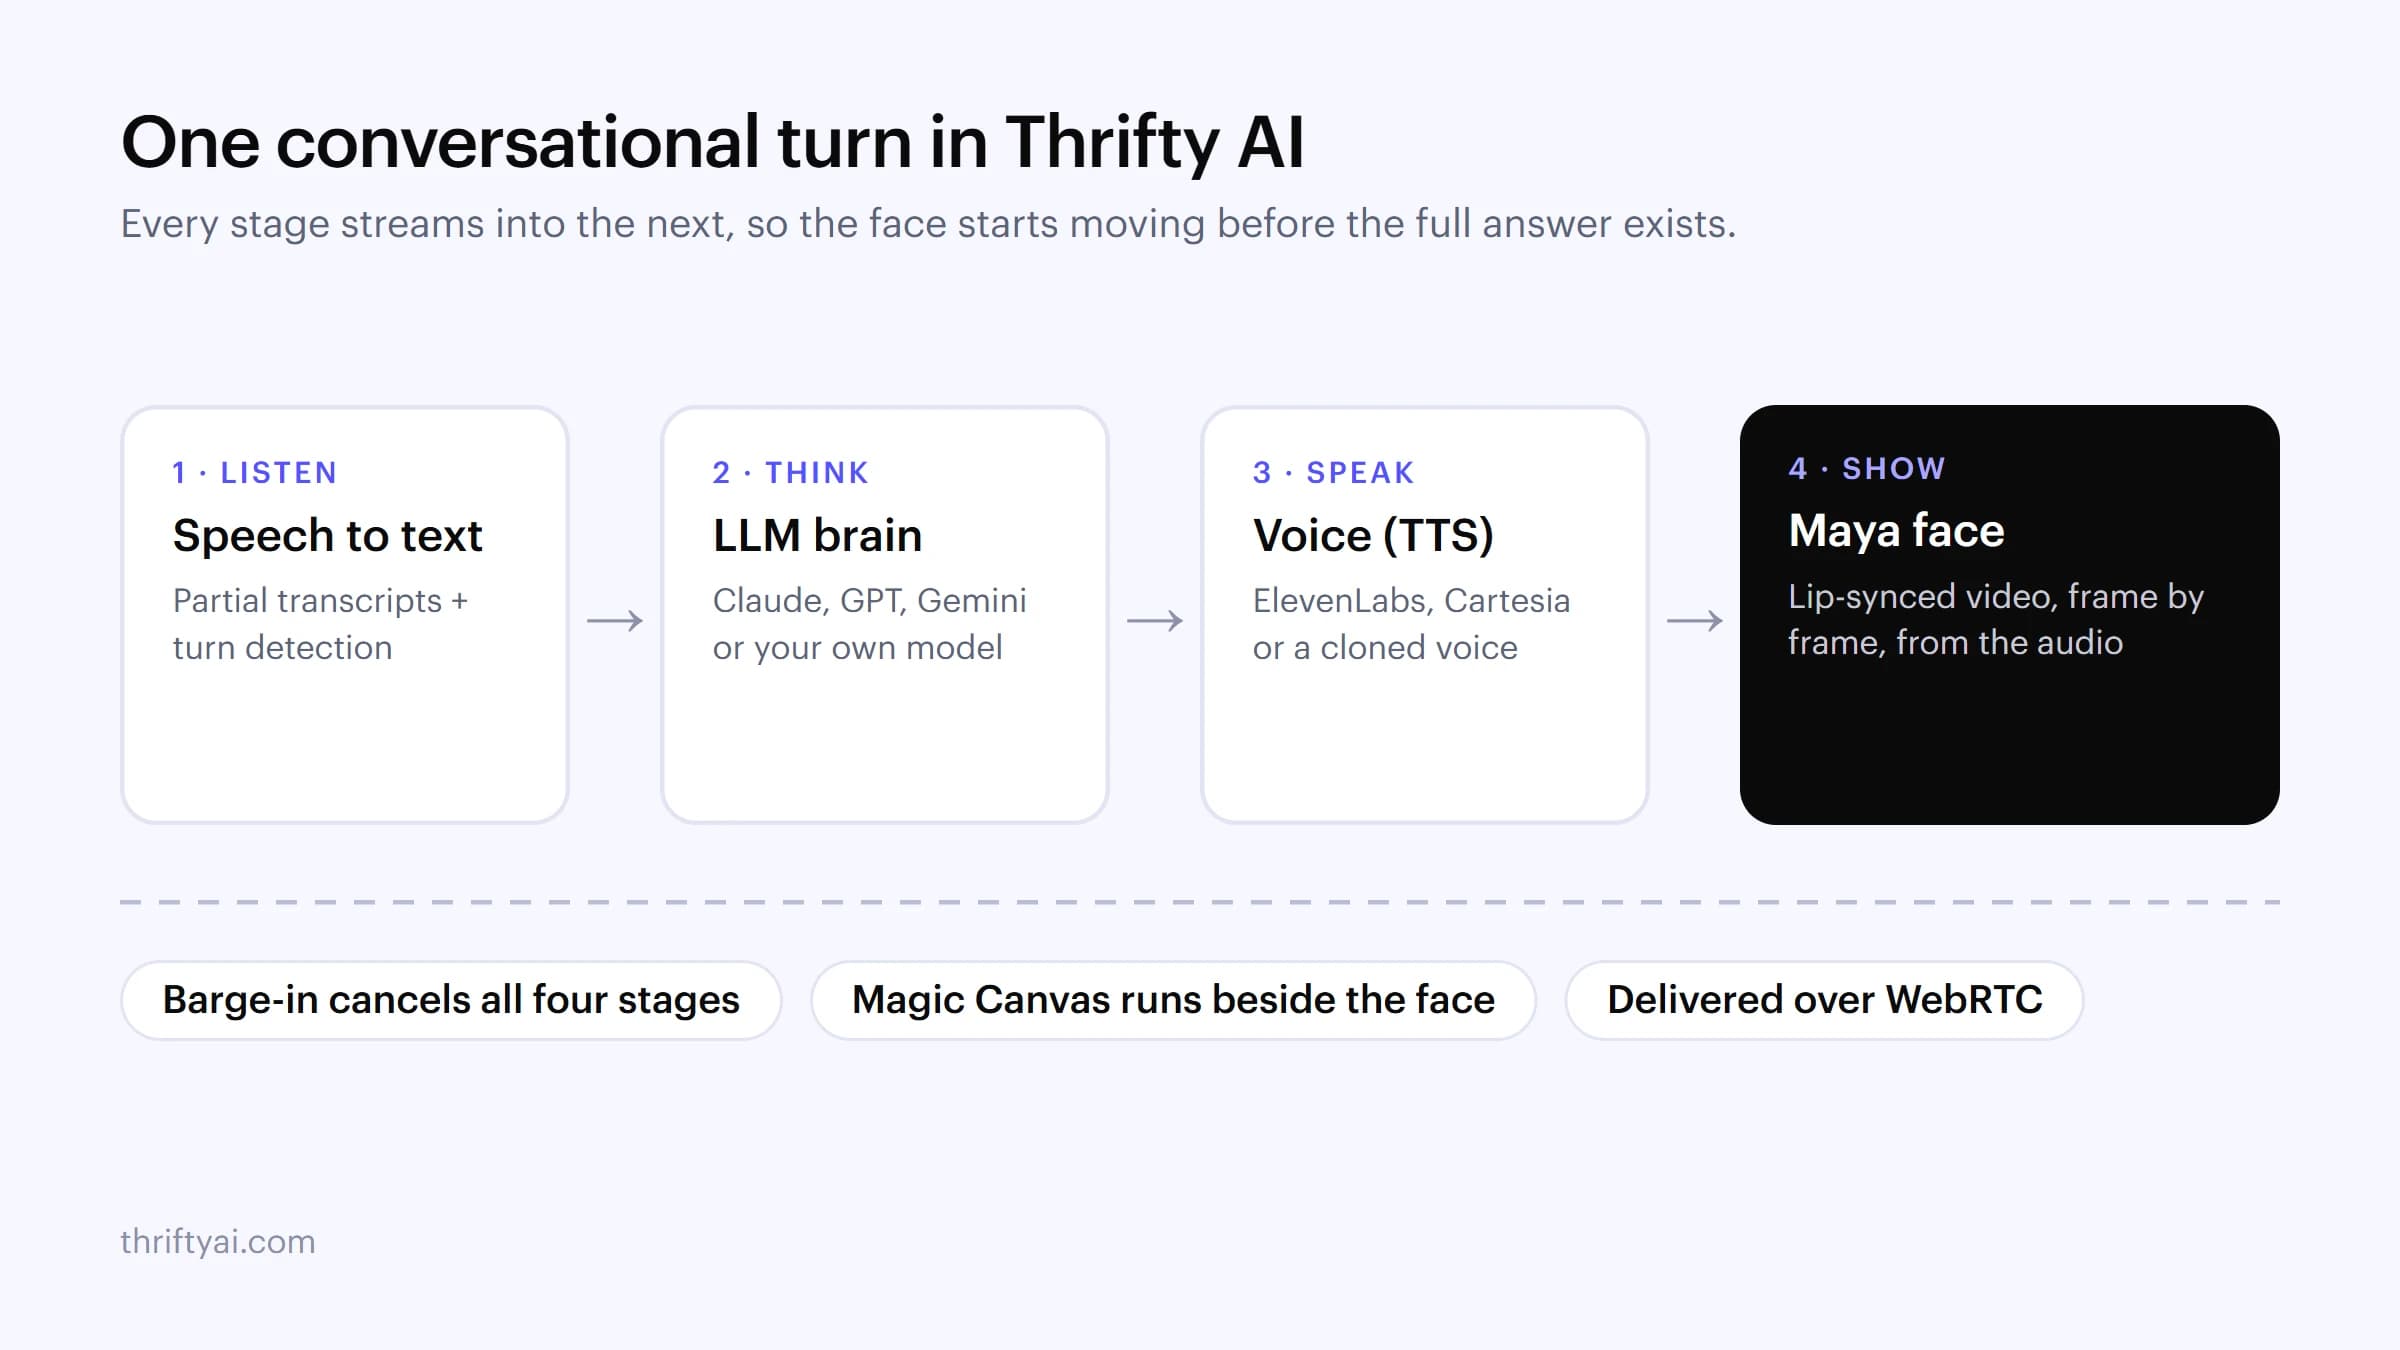
A Thrifty AI human is four things working together: a face, a voice, a brain (the LLM) and a personality (your instructions, knowledge and guardrails). ElevenLabs supplies the voice. Everything else stays the same, so you can switch voices without rebuilding the experience.
- Pick or create the face: one of 100+ stock faces, a custom face from a single photo, or a consented clone from about a minute of video.
- Choose the voice: a Thrifty voice, a cloned voice, or bring your ElevenLabs voice and select v4 Turbo for live sessions.
- Write the personality: system prompt, objectives and guardrails, plus when the AI human should use audio tags (see the patterns below).
- Ground it: upload documents to the knowledge base so answers come from your facts.
- Ship it: share a hosted link, embed it with one script tag, send it into a Google Meet, or deploy it to a kiosk or holobox.
Which audio tag patterns actually work?
Audio tags are inline cues such as [warmly], [whispers], [laughs] or [pause]. ElevenLabs says v4 follows sequences of tags more faithfully than v3. In practice, the risk with tags is not that they fail; it's that an over-eager LLM uses them everywhere and the character becomes a performance. These are the patterns we now ship in our templates.
| Use case | Pattern | Example line |
|---|---|---|
| Support de-escalation | Open calm, stay level, no laughter | [calmly] I can see why that's frustrating. Let's fix it together. |
| Language tutor | Encourage after mistakes, slow down on corrections | [warmly] Nearly! [slowly] Listen once more: bon-jour. |
| Sales roleplay buyer | Sceptical pauses before objections | [pause] [sceptical] That's more than we budgeted for. |
| Hotel concierge | Bright greeting, brief answers | [cheerfully] Good evening! The spa is on level two. |
| Healthcare prep | Soft, unhurried, never playful | [gently] It's normal to feel nervous. Here's what happens next. |
- Limit tags to one or two per reply. Expressiveness is contrast; if every line is emotional, none is.
- Tie tags to conversation state in the system prompt: "use [warmly] after the learner gets something right".
- Ban tags that don't fit the brand. A bank's support agent probably shouldn't [laugh] at a fraud report.
- Note that SSML <break> is disabled in v4; use [pause] or punctuation instead.
One voice, many languages: what changes for global teams?
A common request from our customers is a single brand ambassador who speaks to every market. With v4, ElevenLabs says one voice can keep its identity while taking on native accents across 90+ languages, switching mid-session without changing the voice. Pair that with Thrifty's 70+ conversational languages and the same AI human can greet a guest in English, answer in Hindi and hand over a booking confirmation in Spanish.
Two cautions from our testing. First, check every launch language with a native speaker; quality varies by language even when identity holds. Second, decide who controls the switch. Most deployments should follow the user's language automatically, but kiosks in multilingual countries often work better with an on-screen language picker.
Where should you use v4, and where is it overkill?
| Great fit for v4 / v4 Turbo | Probably overkill |
|---|---|
| Roleplay and training, where emotion is the lesson | Order-status lookups and one-field confirmations |
| Tutoring and coaching that needs warmth and patience | Internal tools where speed beats delivery |
| Brand ambassadors, holobox and event hosts | Very high-volume flows where cost per minute dominates |
| Healthcare and HR conversations that need care | Text-first channels with optional audio |
What about consent and voice cloning?
ElevenLabs supports Instant Voice Clones from short samples and Professional Voice Clones, and requires verified consent from the voice owner. Thrifty applies the same rule to faces: we only create AI humans of real people with their documented consent, and every AI human discloses that it is an AI. If you plan to clone an executive or a trainer, get both the voice and likeness consent signed before you start building.
Frequently asked questions
Can I use ElevenLabs voices with Thrifty AI?
Yes. Thrifty Studios lets you bring ElevenLabs voices to any AI human. For live conversations we recommend Eleven v4 Turbo; for produced videos and course lessons, Eleven v4.
What is the difference between Eleven v4 and v4 Turbo?
Eleven v4 is tuned for produced content where quality matters most. Eleven v4 Turbo is the low-latency model for real-time conversation; ElevenLabs reports about 150 ms median time to first speech.
Does the Thrifty face react to audio tags?
The Maya face is driven by the audio itself, so tags that change the delivery, such as a whisper, a pause or a laugh, change how the face moves. You direct the voice and the face follows.
How many languages does Eleven v4 support?
ElevenLabs says Eleven v4 and v4 Turbo support 90+ languages while keeping a voice's identity. Thrifty AI humans converse in 70+ languages; test each launch language with native speakers.
Does adding a face slow the conversation down?
The face adds a start-up step, which for Maya-2 is 0.90 seconds from first audio to first frame, but every stage streams, so the voice and face start together rather than one after another.
Next up: the same experiment with Cartesia Sonic-3.6, and how to choose between the two.